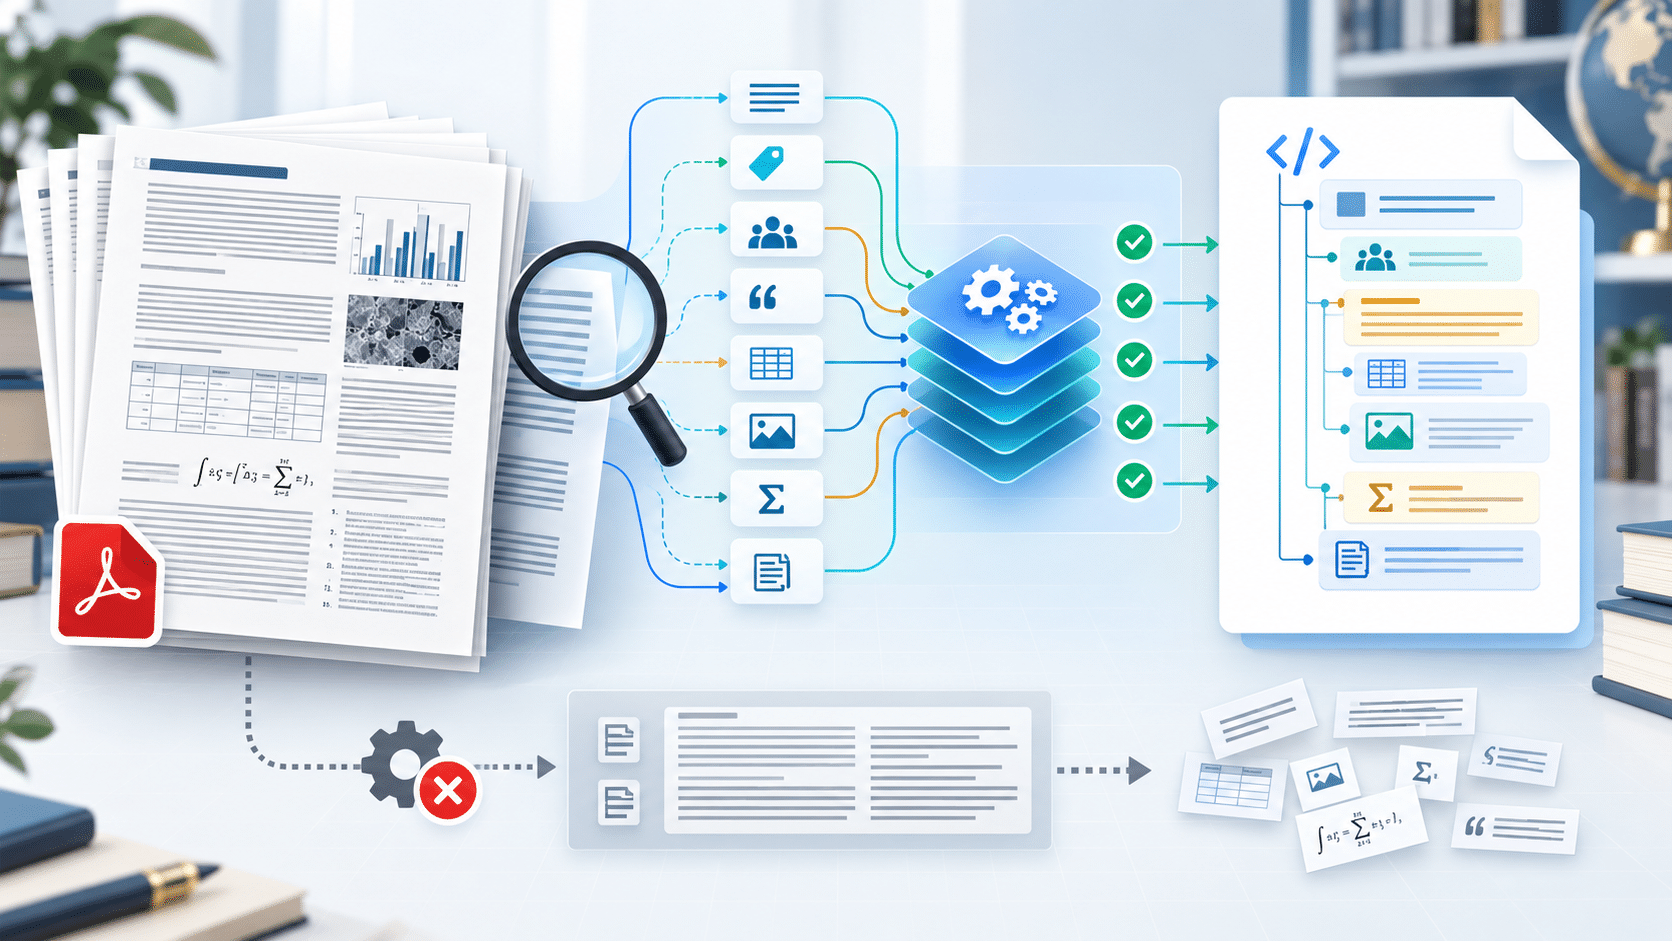
Many journals have years of published articles stored only as PDF files. PDF is convenient for reading, printing, and sharing, but it is not designed to preserve the semantic structure required for modern digital publishing.
When a journal needs to reuse its archive, improve article discoverability, or prepare content for indexing and digital preservation, it may look for a reliable PDF to XML or PDF to JATS solution.
However, not every converter produces reliable scholarly XML. Some tools simply extract visible text from a PDF and place it inside generic XML tags. The result may look like a converted file, but it may not be a valid, editable, or useful JATS document.
PDF to XML Is Not the Same as PDF to JATS
PDF to XML refers to the general process of converting a fixed-layout PDF into structured XML data.
PDF to JATS is more specific. It means transforming the article into XML that follows the Journal Article Tag Suite structure used in scholarly publishing.
A basic XML converter may produce something like:
- A large block of extracted text.
- Random paragraph tags.
- Unstructured author information.
- References without citation relationships.
- Images without captions or descriptions.
- Equations stored only as images.
- Metadata mixed with the article body.
A proper JATS article should identify the role of every important element. The system needs to understand the difference between an article title, an author name, an affiliation, an abstract, a section heading, a figure caption, a table, a citation, and a reference entry.
This is why a file can be technically well-formed XML but still be unsuitable as valid JATS XML.
The Problem with “Just Convert It” Tools
Some tools are built with a simple promise: upload a PDF, click convert, and download XML. While this may seem efficient, the output can contain serious structural problems.
Metadata may be inaccurate
The title, author names, affiliations, DOI, journal name, volume, issue, and page numbers may be extracted incorrectly or placed in the wrong fields.
A small error in an author’s name can affect citation records, author profiles, and article discoverability.
Citations may lose their relationships
In a scholarly article, an in-text citation should be connected to the correct reference entry. A generic converter may extract [1], (Smith, 2020), or superscript numbers as ordinary text without creating a real citation relationship.
The article may look correct visually, but the XML will not understand which reference is being cited.
References can become unusable
References are often split across multiple lines in a PDF. A converter may combine separate references, break one reference into several parts, or place DOI links in the wrong location.
Without structured reference fields, editors may still need to clean and rebuild the reference list manually.
Tables and figures may be damaged
PDFs often position tables and figures visually rather than semantically. During conversion, a table may become a series of unrelated text fragments. Captions may be separated from their figures, and figure placement may become unclear.
For journals with complex tables, charts, or multi-column layouts, automatic extraction requires careful review.
Equations may lose their meaning
A mathematical equation saved as an image is not the same as an editable or structured equation. Symbols, superscripts, subscripts, fractions, and variables may disappear or become unreadable during extraction.
A serious PDF to JATS workflow must provide a way to review and, when necessary, recreate equations using structured mathematical markup.
Why You Should Not Build a Conversion Tool Carelessly
Creating a PDF converter may appear simple if the goal is only to extract text. But building a reliable scholarly conversion tool requires much more than connecting a PDF parser to an XML generator.
A proper tool must understand:
- PDF layout and reading order.
- Article metadata and publishing conventions.
- JATS XML elements and relationships.
- Author and affiliation structures.
- References and citation linking.
- Tables, figures, captions, and supplementary files.
- Equations and special characters.
- Different article types and journal requirements.
- Validation against relevant JATS schemas.
- Future changes in publishing standards.
Without this knowledge, a tool may create output that looks successful while silently damaging the article structure.
The most dangerous result is not an obvious error. It is an XML file that opens successfully but contains incorrect metadata, disconnected citations, missing content, or invalid structural relationships.
What a Reliable PDF to JATS Workflow Should Include
A dependable workflow should combine automated processing with editorial control.
1. Source inspection
The system should first identify whether the PDF contains selectable text, scanned images, multiple columns, tables, figures, footnotes, or complex equations.
A scanned PDF may require OCR, while a digitally generated PDF may be processed through text and layout analysis.
2. Content extraction
The tool should identify the article’s visible components without assuming that every line is an ordinary paragraph.
Titles, authors, affiliations, abstracts, headings, captions, references, and body text should be separated during the extraction stage.
3. Semantic structuring
The extracted content must be mapped into meaningful article elements. This is the stage where generic converters often fail.
The system should distinguish between:
- Front matter and body content.
- Main headings and subsection headings.
- Figures and figure captions.
- Tables and table notes.
- In-text citations and references.
- Author affiliations and correspondence details.
4. Visual editing and correction
Editors should be able to review the converted article in a visual workspace. If the system makes a mistake, users should be able to correct the content and structure without editing raw XML code.
5. Citation and reference review
Every reference should be reviewed, parsed, and connected to the relevant in-text citation. This is especially important for IEEE, APA, Vancouver, and other citation styles.
6. Validation
The final output should be checked against the relevant JATS or publishing schema. Validation helps identify missing required elements, incorrect nesting, malformed references, and other structural problems.
7. Reusable export
The result should be exportable as JATS XML or another required XML format. The structured article should also remain editable so future corrections do not require starting the conversion process again.
How JATS Editor Supports a More Careful Workflow
JATS Editor is designed to make structured article production more manageable for journal teams. Instead of treating conversion as a one-click process, the platform provides a workspace where editorial users can review and organize article content.
A practical workflow can include:
- Importing or preparing article content.
- Reviewing article metadata.
- Organizing headings and sections.
- Editing authors and affiliations.
- Managing references and citations.
- Adding figures, tables, and equations.
- Checking the article structure.
- Preparing PDF layout requirements.
- Exporting publication-ready JATS XML.
The main benefit is editorial visibility. Users can see the article, correct mistakes, and confirm that the output reflects the intended scholarly structure.
Questions to Ask Before Choosing a PDF Converter
Before selecting a PDF to XML or PDF to JATS tool, ask:
- Does it produce valid JATS XML or only generic XML?
- Can editors correct the converted content visually?
- Are citations connected to reference entries?
- Can metadata be reviewed and edited?
- How are tables, figures, and equations handled?
- Is the output validated?
- Can the article be reused and modified later?
- Does the tool support the journal’s publishing workflow?
- Is there technical support when conversion results are incomplete?
If the answer to most of these questions is unclear, the tool may only be performing surface-level text extraction.
Build Quality into the Conversion Process
A reliable PDF to XML workflow should preserve meaning, not just appearance. A reliable PDF to JATS workflow should create structured article content that editors can review, validate, and reuse.
The goal is not to produce an XML file as quickly as possible. The goal is to produce accurate, valid, and publication-ready scholarly content.
JATS Editor helps journal teams move away from careless conversion by combining structured editing, metadata management, citation control, validation, and export in one workflow.
If your journal has PDF archives or needs a more reliable PDF to JATS process, contact the JATS Editor team to discuss your conversion requirements.